

Python文件的写入操作write与writelines方法详解
引言 在Python编程中,文件操作是一个绕不开的基础技能。无论你是处理数据、保存配置,还是记录日志,都离不开文件读写。今天,咱们就来深入聊聊Python中的文件写入操作,特别是write()和writelines()这两个核心方法。别小看它们,用好了能让你的代码既清爽又高效。 文件写入的基础概念
引言
在Python编程中,文件操作是一个绕不开的基础技能。无论你是处理数据、保存配置,还是记录日志,都离不开文件读写。今天,咱们就来深入聊聊Python中的文件写入操作,特别是write()和writelines()这两个核心方法。别小看它们,用好了能让你的代码既清爽又高效。
文件写入的基础概念
在动手之前,先搞清楚文件写入到底是怎么回事。简单说,就是把程序内存中的数据存到磁盘文件里。Python提供了多种写入方式,但最常用的就是这哥俩——write()和writelines()。
文件打开模式
动手写之前,得先知道怎么打开文件。不同模式决定了你是覆盖、追加还是读写:
# 常见的文件写入模式
with open('example.txt', 'w') as file:  # 覆盖写入模式
    pass

with open('example.txt', 'a') as file:  # 追加写入模式
    pass

with open('example.txt', 'r+') as file:  # 读写模式
    pass

with open('example.txt', 'w+') as file:  # 写读模式(会清空文件)
    pass
write() 方法详解
write()是最基本的写入方法,专门用来向文件里塞字符串内容。
基本语法和用法
# write()方法的基本语法
file_object.write(string)
看几个实际例子就明白了:
# 示例1:简单的文本写入
def simple_write_example():
    with open('simple.txt', 'w', encoding='utf-8') as file:
        file.write("Hello, World! \n")
        file.write("这是第二行内容\n")
        file.write("第三行内容")

# 执行函数
simple_write_example()

# 查看结果
with open('simple.txt', 'r', encoding='utf-8') as file:
    content = file.read()
    print(content)
write() 方法的特点
- 只能写入字符串:
write()方法只接受字符串类型的参数 - 返回值:返回实际写入的字符数
- 不自动添加换行符:需要手动添加
\n
# 示例2:write()方法的返回值
def write_return_value():
    with open('return_value.txt', 'w', encoding='utf-8') as file:
        chars_written = file.write("这是一个测试字符串")
        print(f"写入了 {chars_written} 个字符")

write_return_value()
处理不同类型的数据
因为write()只认字符串,其他类型的数据得先转换一下:
# 示例3:处理不同数据类型
def handle_different_types():
    numbers = [1, 2, 3, 4, 5]
    data_dict = {"name": "张三", "age": 25}

    with open('mixed_data.txt', 'w', encoding='utf-8') as file:
        # 写入数字列表
        for num in numbers:
            file.write(str(num) + '\n')

        # 写入字典
        file.write(str(data_dict) + '\n')

        # 写入JSON格式
        import json
        file.write(json.dumps(data_dict, ensure_ascii=False))

handle_different_types()
错误处理和异常情况
写文件时难免会遇到各种坑,提前做好异常处理能省不少事:
# 示例4:错误处理
def safe_write_operation():
    try:
        with open('test.txt', 'w', encoding='utf-8') as file:
            file.write("正常的内容\n")

            # 尝试写入None值(这会产生错误)
            # file.write(None)  # 这行会报错

            # 正确的做法
            file.write(str(None))

    except TypeError as e:
        print(f"类型错误: {e}")
    except PermissionError as e:
        print(f"权限错误: {e}")
    except Exception as e:
        print(f"其他错误: {e}")

safe_write_operation()
writelines() 方法详解
如果有一堆字符串要批量写进去,writelines()就是你的好帮手。
基本语法和用法
# writelines()方法的基本语法
file_object.writelines(sequence_of_strings)
直接上代码:
# 示例5:writelines()基本用法
def basic_writelines_example():
    lines = [
        "第一行内容\n",
        "第二行内容\n",
        "第三行内容\n"
    ]

    with open('lines.txt', 'w', encoding='utf-8') as file:
        file.writelines(lines)

basic_writelines_example()

# 验证结果
with open('lines.txt', 'r', encoding='utf-8') as file:
    content = file.read()
    print(content)
writelines() 的特点
- 接受序列对象:列表、元组、生成器都行
- 不自动添加换行符:别忘了自己加
\n - 批量写入:一次搞定多行,比循环调用
write()快得多
# 示例6:writelines()与不同序列类型
def writelines_with_different_sequences():
    # 使用列表
    list_lines = ["列表项1\n", "列表项2\n", "列表项3\n"]

    # 使用元组
    tuple_lines = ("元组项1\n", "元组项2\n", "元组项3\n")

    # 使用生成器表达式
    generator_lines = (f"生成器项{i}\n" for i in range(1, 4))

    with open('list_output.txt', 'w', encoding='utf-8') as file:
        file.writelines(list_lines)

    with open('tuple_output.txt', 'w', encoding='utf-8') as file:
        file.writelines(tuple_lines)

    with open('generator_output.txt', 'w', encoding='utf-8') as file:
        file.writelines(generator_lines)

writelines_with_different_sequences()
注意事项和常见陷阱
用writelines()时最容易被坑的就是忘记加换行符:
# 示例7:writelines()的注意事项
def writelines_caveats():
    # 错误示例:忘记添加换行符
    bad_lines = ["没有换行符1", "没有换行符2", "没有换行符3"]

    with open('bad_output.txt', 'w', encoding='utf-8') as file:
        file.writelines(bad_lines)

    # 正确示例:正确添加换行符
    good_lines = ["有换行符1\n", "有换行符2\n", "有换行符3\n"]

    with open('good_output.txt', 'w', encoding='utf-8') as file:
        file.writelines(good_lines)

    # 使用列表推导式简化
    data = ["项目A", "项目B", "项目C"]
    formatted_lines = [line + '\n' for line in data]

    with open('formatted_output.txt', 'w', encoding='utf-8') as file:
        file.writelines(formatted_lines)

writelines_caveats()
write() vs writelines() 对比分析
到底什么时候用write(),什么时候用writelines()?咱们来掰扯清楚。
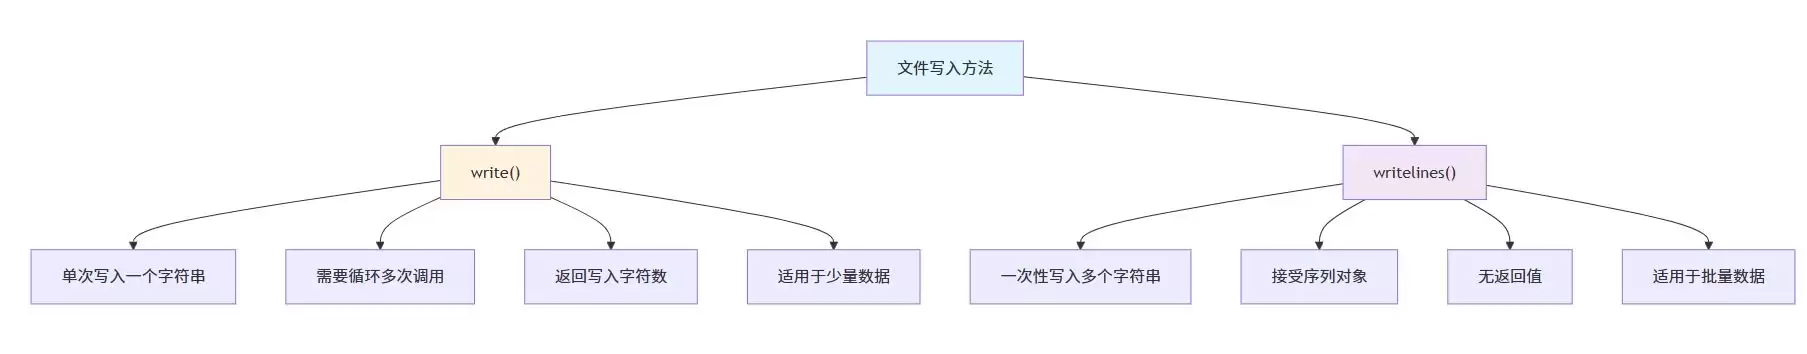
性能比较
空口无凭,跑个性能测试看看:
import time

# 示例8:性能比较
def performance_comparison():
    # 准备测试数据
    test_data = [f"这是第{i}行数据\n" for i in range(10000)]

    # 测试write()方法
    start_time = time.time()
    with open('write_test.txt', 'w', encoding='utf-8') as file:
        for line in test_data:
            file.write(line)
    write_time = time.time() - start_time

    # 测试writelines()方法
    start_time = time.time()
    with open('writelines_test.txt', 'w', encoding='utf-8') as file:
        file.writelines(test_data)
    writelines_time = time.time() - start_time

    print(f"write()方法耗时: {write_time:.4f}秒")
    print(f"writelines()方法耗时: {writelines_time:.4f}秒")
    print(f"writelines()比write()快 {write_time/writelines_time:.2f}倍")

performance_comparison()
使用场景选择
不同场景选不同方法,这是经验之谈:
# 示例9:根据不同场景选择方法
def scenario_based_selection():
    # 场景1:写入单条信息 - 使用write()
    def log_single_message(message):
        with open('log.txt', 'a', encoding='utf-8') as file:
            timestamp = time.strftime("%Y-%m-%d %H:%M:%S")
            file.write(f"[{timestamp}] {message}\n")

    # 场景2:批量写入数据 - 使用writelines()
    def export_user_list(users):
        user_lines = [f"{user['id']},{user['name']},{user['email']}\n"
                     for user in users]
        with open('users.csv', 'w', encoding='utf-8') as file:
            file.writelines(user_lines)

    # 模拟数据
    users = [
        {"id": 1, "name": "张三", "email": "zhangsan@example.com"},
        {"id": 2, "name": "李四", "email": "lisi@example.com"},
        {"id": 3, "name": "王五", "email": "wangwu@example.com"}
    ]

    # 执行示例
    log_single_message("用户登录成功")
    export_user_list(users)

scenario_based_selection()
实际应用案例
理论说完了,来看看这两个方法在实际项目中怎么用。
日志系统实现
# 示例10:简单日志系统
class SimpleLogger:
    def __init__(self, filename):
        self.filename = filename

    def log(self, level, message):
        timestamp = time.strftime("%Y-%m-%d %H:%M:%S")
        log_entry = f"[{timestamp}] [{level.upper()}] {message}\n"

        # 使用write()方法记录单条日志
        with open(self.filename, 'a', encoding='utf-8') as file:
            file.write(log_entry)

    def bulk_log(self, entries):
        # 使用writelines()方法批量记录日志
        formatted_entries = []
        for level, message in entries:
            timestamp = time.strftime("%Y-%m-%d %H:%M:%S")
            formatted_entries.append(f"[{timestamp}] [{level.upper()}] {message}\n")

        with open(self.filename, 'a', encoding='utf-8') as file:
            file.writelines(formatted_entries)

# 使用示例
logger = SimpleLogger('app.log')
logger.log('info', '应用程序启动')
logger.log('debug', '调试信息')

bulk_entries = [
    ('warning', '警告信息1'),
    ('error', '错误信息1'),
    ('info', '普通信息1')
]
logger.bulk_log(bulk_entries)
数据导出功能
# 示例11:数据导出到CSV文件
def export_to_csv(data, filename):
    """
    将数据导出到CSV文件
    :param data: 包含字典的列表
    :param filename: 输出文件名
    """
    if not data:
        return

    # 获取表头
    headers = list(data[0].keys())

    # 准备所有行
    all_lines = []

    # 添加表头
    all_lines.append(','.join(headers) + '\n')

    # 添加数据行
    for row in data:
        values = [str(row.get(header, '')) for header in headers]
        all_lines.append(','.join(values) + '\n')

    # 使用writelines()一次性写入所有数据
    with open(filename, 'w', encoding='utf-8') as file:
        file.writelines(all_lines)

# 测试数据
employees = [
    {"姓名": "张三", "部门": "技术部", "工资": 8000},
    {"姓名": "李四", "部门": "销售部", "工资": 7000},
    {"姓名": "王五", "部门": "人事部", "工资": 6000}
]

export_to_csv(employees, 'employees.csv')
配置文件管理
# 示例12:配置文件管理
class ConfigManager:
    def __init__(self, config_file):
        self.config_file = config_file
        self.config_data = {}
        self.load_config()

    def load_config(self):
        """加载配置文件"""
        try:
            with open(self.config_file, 'r', encoding='utf-8') as file:
                for line in file:
                    if '=' in line and not line.strip().startswith('#'):
                        key, value = line.strip().split('=', 1)
                        self.config_data[key.strip()] = value.strip()
        except FileNotFoundError:
            # 如果文件不存在,创建默认配置
            self.create_default_config()

    def create_default_config(self):
        """创建默认配置"""
        default_config = {
            'database_host': 'localhost',
            'database_port': '5432',
            'debug_mode': 'False',
            'max_connections': '100'
        }

        # 使用write()方法逐行写入配置
        with open(self.config_file, 'w', encoding='utf-8') as file:
            file.write("# 应用程序配置文件\n")
            file.write("# 创建时间: {}\n\n".format(time.strftime("%Y-%m-%d %H:%M:%S")))

            for key, value in default_config.items():
                file.write(f"{key}={value}\n")

        self.config_data = default_config

    def update_config(self, updates):
        """更新配置"""
        self.config_data.update(updates)
        self.save_config()

    def save_config(self):
        """保存配置到文件"""
        # 准备配置行
        config_lines = ["# 配置文件\n"]
        config_lines.append(f"# 最后更新: {time.strftime('%Y-%m-%d %H:%M:%S')}\n\n")

        for key, value in self.config_data.items():
            config_lines.append(f"{key}={value}\n")

        # 使用writelines()保存配置
        with open(self.config_file, 'w', encoding='utf-8') as file:
            file.writelines(config_lines)

# 使用示例
config_manager = ConfigManager('app.conf')
print("当前配置:", config_manager.config_data)

# 更新配置
config_manager.update_config({
    'database_host': '192.168.1.100',
    'debug_mode': 'True'
})
高级技巧和最佳实践
编码处理
处理中文或其他非ASCII字符时,编码设置是第一个要注意的坑:
# 示例13:编码处理最佳实践
def encoding_best_practices():
    # 中文文本
    chinese_text = "你好,世界!这是中文测试内容。"

    # 英文文本
    english_text = "Hello, World! This is English test content."

    # 混合文本
    mixed_text = "混合文本 Mixed Text ?"

    # 不同编码格式的写入
    encodings = ['utf-8', 'gbk', 'ascii']

    for encoding in encodings:
        try:
            filename = f'test_{encoding}.txt'
            with open(filename, 'w', encoding=encoding) as file:
                file.write(chinese_text + '\n')
                file.write(english_text + '\n')
                file.write(mixed_text + '\n')
            print(f"使用 {encoding} 编码写入成功")
        except UnicodeEncodeError as e:
            print(f"使用 {encoding} 编码失败: {e}")
        except Exception as e:
            print(f"其他错误: {e}")

encoding_best_practices()
缓冲区控制
缓冲区这玩意儿调好了能显著提升写入效率:
# 示例14:缓冲区控制
import os

def buffer_control_demo():
    # 无缓冲写入
    with open('no_buffer.txt', 'w', buffering=0, encoding='utf-8') as file:
        file.write("无缓冲写入\n")

    # 行缓冲写入
    with open('line_buffer.txt', 'w', buffering=1, encoding='utf-8') as file:
        file.write("行缓冲写入\n")

    # 自定义缓冲区大小
    with open('custom_buffer.txt', 'w', buffering=8192, encoding='utf-8') as file:
        file.write("自定义缓冲区写入\n")

    # 检查文件大小
    files = ['no_buffer.txt', 'line_buffer.txt', 'custom_buffer.txt']
    for filename in files:
        if os.path.exists(filename):
            size = os.path.getsize(filename)
            print(f"{filename}: {size} 字节")

buffer_control_demo()
上下文管理器的重要性
用with语句打开文件,不仅能省掉手动close()的麻烦,还能自动处理异常,这是写Python文件操作的标配:
# 示例15:上下文管理器的重要性
import atexit

class FileManager:
    def __init__(self, filename, mode):
        self.filename = filename
        self.mode = mode
        self.file = None

    def __enter__(self):
        print(f"打开文件: {self.filename}")
        self.file = open(self.filename, self.mode, encoding='utf-8')
        return self.file

    def __exit__(self, exc_type, exc_val, exc_tb):
        if self.file:
            print(f"关闭文件: {self.filename}")
            self.file.close()
        if exc_type:
            print(f"发生异常: {exc_type.__name__}: {exc_val}")
        return False  # 不抑制异常

# 使用自定义上下文管理器
def custom_context_manager_demo():
    try:
        with FileManager('context_test.txt', 'w') as file:
            file.write("使用自定义上下文管理器\n")
            file.write("确保文件被正确关闭\n")
            # 故意引发异常来测试
            # raise ValueError("测试异常")
    except ValueError as e:
        print(f"捕获到异常: {e}")

custom_context_manager_demo()
性能优化策略
批量写入优化
数据量大时,选对方法能让你省下不少时间:
# 示例16:批量写入优化
import time
from io import StringIO

def batch_write_optimization():
    # 准备大量测试数据
    large_data = [f"数据行 {i}" for i in range(100000)]

    # 方法1:逐行写入(较慢)
    start_time = time.time()
    with open('method1.txt', 'w', encoding='utf-8') as file:
        for line in large_data:
            file.write(line + '\n')
    method1_time = time.time() - start_time

    # 方法2:使用writelines(较快)
    start_time = time.time()
    formatted_data = [line + '\n' for line in large_data]
    with open('method2.txt', 'w', encoding='utf-8') as file:
        file.writelines(formatted_data)
    method2_time = time.time() - start_time

    # 方法3:使用StringIO缓冲(最快)
    start_time = time.time()
    buffer = StringIO()
    for line in large_data:
        buffer.write(line + '\n')

    with open('method3.txt', 'w', encoding='utf-8') as file:
        file.write(buffer.getvalue())

    method3_time = time.time() - start_time

    print(f"逐行写入耗时: {method1_time:.4f}秒")
    print(f"writelines耗时: {method2_time:.4f}秒")
    print(f"StringIO缓冲耗时: {method3_time:.4f}秒")

batch_write_optimization()
内存映射文件
对于超大型文件的修改,内存映射是一种更高效的方式,但这里只做概念介绍:
# 示例17:内存映射文件示例
import mmap

def memory_mapped_file_demo():
    # 创建一个大文件
    large_content = "这是重复的内容。\n" * 10000

    # 常规写入
    with open('regular_file.txt', 'w', encoding='utf-8') as file:
        file.write(large_content)

    # 内存映射写入(适用于已存在的大文件的修改)
    # 注意:这里只是演示概念,实际应用需要更复杂的逻辑
    print("常规文件写入完成")

memory_mapped_file_demo()
错误处理和调试技巧
完善的异常处理
写代码不写异常处理,就像开车不系安全带。来看一个健壮的文件写入函数:
# 示例18:完善的异常处理
import logging

# 配置日志
logging.basicConfig(level=logging.INFO, format='%(asctime)s - %(levelname)s - %(message)s')

def robust_file_writer(filename, content, encoding='utf-8'):
    """
    健壮的文件写入函数
    """
    try:
        # 检查参数
        if not isinstance(filename, str) or not filename:
            raise ValueError("文件名不能为空")

        if not isinstance(content, (str, list, tuple)):
            raise TypeError("内容必须是字符串或序列类型")

        # 确保目录存在
        import os
        directory = os.path.dirname(filename)
        if directory and not os.path.exists(directory):
            os.makedirs(directory)

        # 根据内容类型选择写入方法
        with open(filename, 'w', encoding=encoding) as file:
            if isinstance(content, str):
                # 单字符串使用write()
                chars_written = file.write(content)
                logging.info(f"成功写入 {chars_written} 个字符到 {filename}")
            else:
                # 序列使用writelines()
                if content and not isinstance(content[0], str):
                    # 转换非字符串元素
                    content = [str(item) for item in content]

                file.writelines(content)
                logging.info(f"成功写入序列到 {filename}")

        return True

    except PermissionError:
        logging.error(f"权限不足,无法写入文件: {filename}")
        return False
    except FileNotFoundError:
        logging.error(f"路径不存在: {filename}")
        return False
    except UnicodeEncodeError as e:
        logging.error(f"编码错误: {e}")
        return False
    except OSError as e:
        logging.error(f"操作系统错误: {e}")
        return False
    except Exception as e:
        logging.error(f"未预期的错误: {e}")
        return False

# 测试健壮的文件写入函数
test_cases = [
    ("test1.txt", "简单的字符串内容"),
    ("test2.txt", ["第一行\n", "第二行\n", "第三行\n"]),
    ("subdir/test3.txt", "包含子目录的文件"),
    ("", "空文件名"),  # 这会触发错误
    ("test4.txt", 123),  # 这会触发类型错误
]

for filename, content in test_cases:
    result = robust_file_writer(filename, content)
    print(f"写入 {filename}: {'成功' if result else '失败'}")
调试技巧
遇到问题别慌,加个调试信息就能快速定位:
# 示例19:调试技巧
def debug_file_operations():
    """
    文件操作调试示例
    """
    import traceback

    def write_with_debug_info(filename, content):
        print(f"=== 开始写入文件: {filename} ===")
        print(f"内容类型: {type(content)}")
        print(f"内容长度: {len(content) if hasattr(content, '__len__') else 'N/A'}")

        try:
            if isinstance(content, str):
                print("使用write()方法")
                with open(filename, 'w', encoding='utf-8') as file:
                    result = file.write(content)
                    print(f"实际写入字符数: {result}")
            else:
                print("使用writelines()方法")
                print(f"序列长度: {len(content)}")
                print(f"前3个元素: {content[:3]}")
                with open(filename, 'w', encoding='utf-8') as file:
                    file.writelines(content)

            print(f"=== 文件写入成功 ===\n")

        except Exception as e:
            print(f"=== 发生错误 ===")
            print(f"错误类型: {type(e).__name__}")
            print(f"错误信息: {e}")
            print("详细堆栈:")
            traceback.print_exc()
            print(f"=== 错误结束 ===\n")

    # 测试用例
    test_cases = [
        ("debug1.txt", "正常字符串"),
        ("debug2.txt", ["行1\n", "行2\n"]),
        ("debug3.txt", None),  # 这会导致错误
    ]

    for filename, content in test_cases:
        write_with_debug_info(filename, content)

debug_file_operations()
实用工具函数
通用文件写入工具
把常用的写入需求封装成工具类,以后直接用:
# 示例20:通用文件写入工具
class FileWriter:
    """
    通用文件写入工具类
    """

    @staticmethod
    def write_text(filename, content, encoding='utf-8', mode='w'):
        """
        写入文本内容
        """
        with open(filename, mode, encoding=encoding) as file:
            if isinstance(content, str):
                return file.write(content)
            else:
                file.writelines(content)

    @staticmethod
    def append_lines(filename, lines, encoding='utf-8'):
        """
        追加多行内容
        """
        if isinstance(lines, str):
            lines = [lines]

        formatted_lines = [line if line.endswith('\n') else line + '\n'
                          for line in lines]

        with open(filename, 'a', encoding=encoding) as file:
            file.writelines(formatted_lines)

    @staticmethod
    def write_formatted(filename, template, data, encoding='utf-8'):
        """
        写入格式化内容
        """
        content = template.format(**data)
        with open(filename, 'w', encoding=encoding) as file:
            file.write(content)

    @staticmethod
    def write_json(filename, data, indent=2, encoding='utf-8'):
        """
        写入JSON数据
        """
        import json
        with open(filename, 'w', encoding=encoding) as file:
            json.dump(data, file, indent=indent, ensure_ascii=False)

    @staticmethod
    def atomic_write(filename, content, encoding='utf-8'):
        """
        原子写入(避免写入过程中断导致文件损坏)
        """
        import tempfile
        import shutil

        # 创建临时文件
        temp_fd, temp_path = tempfile.mkstemp(dir=os.path.dirname(filename) or '.')

        try:
            # 写入临时文件
            with os.fdopen(temp_fd, 'w', encoding=encoding) as temp_file:
                if isinstance(content, str):
                    temp_file.write(content)
                else:
                    temp_file.writelines(content)

            # 原子性地替换原文件
            shutil.move(temp_path, filename)

        except Exception:
            # 清理临时文件
            try:
                os.unlink(temp_path)
            except:
                pass
            raise

# 使用示例
def utility_functions_demo():
    writer = FileWriter()

    # 写入文本
    writer.write_text('utility1.txt', '这是普通文本内容')

    # 追加多行
    writer.append_lines('utility2.txt', ['追加行1', '追加行2'])

    # 写入格式化内容
    template = """
用户名: {username}
邮箱: {email}
注册时间: {reg_time}
"""
    data = {
        'username': '张三',
        'email': 'zhangsan@example.com',
        'reg_time': '2023-01-01'
    }
    writer.write_formatted('user_info.txt', template, data)

    # 写入JSON
    user_data = {
        'users': [
            {'id': 1, 'name': '张三', 'active': True},
            {'id': 2, 'name': '李四', 'active': False}
        ]
    }
    writer.write_json('users.json', user_data)

    # 原子写入
    writer.atomic_write('atomic.txt', '原子写入的内容')

utility_functions_demo()
与其他模块的集成
与CSV模块的配合使用
# 示例21:与CSV模块配合使用
import csv

def csv_integration_demo():
    # 准备数据
    data = [
        ['姓名', '年龄', '城市'],
        ['张三', '25', '北京'],
        ['李四', '30', '上海'],
        ['王五', '28', '广州']
    ]

    # 方法1:直接写入CSV(推荐)
    with open('direct.csv', 'w', newline='', encoding='utf-8') as file:
        writer = csv.writer(file)
        writer.writerows(data)

    # 方法2:使用write()和writelines()手动处理
    csv_lines = []
    for row in data:
        csv_lines.append(','.join(row) + '\n')

    with open('manual.csv', 'w', encoding='utf-8') as file:
        file.writelines(csv_lines)

csv_integration_demo()
与JSON模块的配合使用
# 示例22:与JSON模块配合使用
import json

def json_integration_demo():
    # 复杂数据结构
    complex_data = {
        "公司": "科技有限公司",
        "员工": [
            {
                "id": 1,
                "姓名": "张三",
                "技能": ["Python", "Java", "JavaScript"],
                "薪资": 8000
            },
            {
                "id": 2,
                "姓名": "李四",
                "技能": ["Python", "Go"],
                "薪资": 9000
            }
        ],
        "成立时间": "2020-01-01"
    }

    # 方法1:使用json.dump()(推荐)
    with open('structured.json', 'w', encoding='utf-8') as file:
        json.dump(complex_data, file, indent=2, ensure_ascii=False)

    # 方法2:手动格式化后使用write()
    formatted_json = json.dumps(complex_data, indent=2, ensure_ascii=False)
    with open('manual_formatted.json', 'w', encoding='utf-8') as file:
        file.write(formatted_json)

json_integration_demo()
最佳实践总结
通过前面的学习,可以总结出一些重要的经验:
选择合适的写入方法
# 示例23:方法选择指南
def method_selection_guide():
    """
    写入方法选择指南
    """

    scenarios = {
        "单次写入少量文本": {
            "推荐方法": "write()",
            "原因": "简单直接,适合单次操作",
            "示例": "file.write('Hello World')"
        },

        "批量写入多行文本": {
            "推荐方法": "writelines()",
            "原因": "性能更好,代码更简洁",
            "示例": "file.writelines(['line1\n', 'line2\n'])"
        },

        "写入结构化数据": {
            "推荐方法": "专用库(如json、csv)",
            "原因": "处理复杂格式,避免手动拼接",
            "示例": "json.dump(data, file)"
        },

        "写入二进制数据": {
            "推荐方法": "write() with bytes",
            "原因": "直接支持字节数据",
            "示例": "file.write(b'binary data')"
        }
    }

    for scenario, info in scenarios.items():
        print(f"\n场景: {scenario}")
        print(f"推荐方法: {info['推荐方法']}")
        print(f"原因: {info['原因']}")
        print(f"示例: {info['示例']}")

method_selection_guide()
性能优化建议
# 示例24:性能优化建议
def performance_tips():
    """
    性能优化建议
    """

    tips = [
        "1. 大量数据写入时优先使用writelines()而不是循环调用write()",
        "2. 使用StringIO作为中间缓冲区可以提升性能",
        "3. 合理设置缓冲区大小",
        "4. 避免频繁打开/关闭文件",
        "5. 使用上下文管理器确保资源正确释放",
        "6. 考虑使用原子写入避免数据损坏"
    ]

    print("文件写入性能优化建议:")
    for tip in tips:
        print(tip)

performance_tips()
总结与展望
到此,我们把Python中文件写入的两个核心方法——write()和writelines()——从头到尾梳理了一遍。它们各有侧重:
write()简单直接,适合单次写入操作writelines()性能优越,适合批量写入操作
实际开发中,建议:
- 根据具体需求选择合适的方法
- 注意编码处理和异常处理
- 遵循最佳实践,编写健壮的代码
- 在性能要求较高的场景下,考虑使用更高级的优化技术
Python的文件操作功能强大又灵活,把这些基础打扎实了,后面的路会走得更稳。

学习如何使用Python高效删除列表中的重复元素。本文提供5种常见方法的代码示例,涵盖保持顺序与不保持顺序的场景,适合初学者和进阶开发者参考。

详细讲解使用Python编写Web接口的核心步骤与完整代码示例,涵盖环境准备、路由定义、数据校验、服务启动及调试测试方法。

介绍如何利用编程工具读取和解析Word文档(docx格式),涵盖基础文本提取代码示例、结构化数据处理逻辑,以及处理复杂排版时的技术局限与替代方案。

详细讲解在Python中调用C语言代码提升性能的完整实践指南,包含原理分析、编译步骤、ctypes与CFFI具体实现、性能对比及常见陷阱。


客观对比Python与C语言在心智负担、底层机制与学习反馈上的核心差异,提供清晰有据的选择标准与切实的入门学习路径。


针对大数据工程场景,系统对比Java、Scala与Python在执行性能、生态结合、开发效率和维护成本上的核心差异,给出清晰的架构选型依据与落地方案。

本篇LangGraph Python中文入门教程详解,系统梳理StateGraph状态机定义、节点编写、边与条件路由、检查点持久化(MemorySaver)等核心机制,提供从环境安装到完整循环智能体构建的代码示例与实操指导。

面向后端开发者,基于 Python 官方文档说明如何在 Windows 上安装 Python、创建 venv 虚拟环境及使用 pip 管理依赖。包含可复制命令、验证方法及工具选择边界,避免常见配置误区。





火山引擎是字节跳动旗下企业级云与AI服务平台。聚焦大模型核心能力,依托字节自研豆包多模态大模型,凭借火山方舟一站式平台,提供模型精调、推理部署、智能应用搭建等全链路服务,结合高性能AI算力,助力各行业快速落地大模型数字化与智能化应用。



