

使用scikit-learn为PyTorch 模型进行超参数网格搜索
scikit-learn是Python中最好的机器学习库,而PyTorch又为我们构建模型提供了方便的操作,能否将它们的优点整合起来呢?在本文中,我们将介绍如何使用scikit-learn中的网格搜索功能来调整PyTorch深度学习模型的超参数:如何包装PyTorch模型以用于scikit-learn以及如何使用网格搜索如何网格搜索常见的神经网络参数,如学习率、Dropout、epochs、神经元数在自己的项目上定义自己的超参数调优实验如何在scikit-learn中使用PyTorch
scikit-learn是Python中最好的机器学习库,而PyTorch又为我们构建模型提供了方便的操作,能否将它们的优点整合起来呢?在本文中,我们将介绍如何使用 scikit-learn中的网格搜索功能来调整 PyTorch 深度学习模型的超参数:
- 如何包装 PyTorch 模型以用于 scikit-learn 以及如何使用网格搜索
- 如何网格搜索常见的神经网络参数,如学习率、Dropout、epochs、神经元数
- 在自己的项目上定义自己的超参数调优实验
如何在 scikit-learn 中使用 PyTorch 模型
要让PyTorch 模型可以在 scikit-learn 中使用的一个最简单的方法是使用skorch包。这个包为 PyTorch 模型提供与 scikit-learn 兼容的 API。 在skorch中,有分类神经网络的NeuralNetClassifier和回归神经网络的NeuralNetRegressor。
pip install skorch
要使用这些包装器,必须使用 nn.Module 将 PyTorch 模型定义为类,然后在构造 NeuralNetClassifier 类时将类的名称传递给模块参数。 例如:
class MyClassifier(nn.Module):
def __init__(self):
super().__init__()
...

def forward(self, x):
...
return x

 # create the skorch wrapper
 model = NeuralNetClassifier(
module=MyClassifier
 )
NeuralNetClassifier 类的构造函数可以获得传递给 model.fit() 调用的参数(在 scikit-learn 模型中调用训练循环的方法),例如轮次数和批量大小等。 例如:
model = NeuralNetClassifier(
module=MyClassifier,
max_epochs=150,
batch_size=10
 )
NeuralNetClassifier类的构造函数也可以接受新的参数,这些参数可以传递给你的模型类的构造函数,要求是必须在它前面加上module__(两个下划线)。这些新参数可能在构造函数中带有默认值,但当包装器实例化模型时,它们将被覆盖。例如:
import torch.nn as nn
 from skorch import NeuralNetClassifier

 class SonarClassifier(nn.Module):
def __init__(self, n_layers=3):
super().__init__()
self.layers = []
self.acts = []
for i in range(n_layers):
self.layers.append(nn.Linear(60, 60))
self.acts.append(nn.ReLU())
self.add_module(f"layer{i}", self.layers[-1])
self.add_module(f"act{i}", self.acts[-1])
self.output = nn.Linear(60, 1)

def forward(self, x):
for layer, act in zip(self.layers, self.acts):
x = act(layer(x))
x = self.output(x)
return x

 model = NeuralNetClassifier(
module=SonarClassifier,
max_epochs=150,
batch_size=10,
module__n_layers=2
 )
我们可以通过初始化一个模型并打印来验证结果:
print(model.initialize()) #结果如下:[initialized]( module_=SonarClassifier( (layer0): Linear(in_features=60, out_features=60, bias=True) (act0): ReLU() (layer1): Linear(in_features=60, out_features=60, bias=True) (act1): ReLU() (output): Linear(in_features=60, out_features=1, bias=True) ), )
在scikit-learn中使用网格搜索
网格搜索是一种模型超参数优化技术。它只是简单地穷尽超参数的所有组合,并找到给出最佳分数的组合。在scikit-learn中,GridSearchCV类提供了这种技术。在构造这个类时,必须在param_grid参数中提供一个超参数字典。这是模型参数名和要尝试的值数组的映射。
默认使用精度作为优化的分数,但其他分数可以在GridSearchCV构造函数的score参数中指定。GridSearchCV将为每个参数组合构建一个模型进行评估。并且使用默认的3倍交叉验证,这些都是可以通过参数来进行设置的。
下面是定义一个简单网格搜索的例子:
param_grid = {
'epochs': [10,20,30]
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, Y)
通过将GridSearchCV构造函数中的n_jobs参数设置为 -1表示将使用机器上的所有核心。否则,网格搜索进程将只在单线程中运行,这在多核cpu中较慢。
运行完毕就可以在grid.fit()返回的结果对象中访问网格搜索的结果。best_score提供了在优化过程中观察到的最佳分数,best_params_描述了获得最佳结果的参数组合。
示例问题描述
我们的示例都将在一个小型标准机器学习数据集上进行演示,该数据集是一个糖尿病发作分类数据集。这是一个小型数据集,所有的数值属性都很容易处理。
如何调优批大小和训练的轮次
在第一个简单示例中,我们将介绍如何调优批大小和拟合网络时使用的epoch数。
我们将简单评估从10到100的不批大小,代码清单如下所示:
import random
 import numpy as np
 import torch
 import torch.nn as nn
 import torch.optim as optim
 from skorch import NeuralNetClassifier
 from sklearn.model_selection import GridSearchCV

 # load the dataset, split into input (X) and output (y) variables
 dataset = np.loadtxt('pima-indians-diabetes.csv', delimiter=',')
 X = dataset[:,0:8]
 y = dataset[:,8]
 X = torch.tensor(X, dtype=torch.float32)
 y = torch.tensor(y, dtype=torch.float32).reshape(-1, 1)

 # PyTorch classifier
 class PimaClassifier(nn.Module):
def __init__(self):
super().__init__()
self.layer = nn.Linear(8, 12)
self.act = nn.ReLU()
self.output = nn.Linear(12, 1)
self.prob = nn.Sigmoid()

def forward(self, x):
x = self.act(self.layer(x))
x = self.prob(self.output(x))
return x

 # create model with skorch
 model = NeuralNetClassifier(
PimaClassifier,
criterinotallow=nn.BCELoss,
optimizer=optim.Adam,
verbose=False
 )

 # define the grid search parameters
 param_grid = {
'batch_size': [10, 20, 40, 60, 80, 100],
'max_epochs': [10, 50, 100]
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, y)

 # summarize results
 print("Best: %f using %s" % (grid_result.best_score_, grid_result.best_params_))
 means = grid_result.cv_results_['mean_test_score']
 stds = grid_result.cv_results_['std_test_score']
 params = grid_result.cv_results_['params']
 for mean, stdev, param in zip(means, stds, params):
print("%f (%f) with: %r" % (mean, stdev, param))
结果如下:
Best: 0.714844 using {'batch_size': 10, 'max_epochs': 100}
 0.665365 (0.020505) with: {'batch_size': 10, 'max_epochs': 10}
 0.588542 (0.168055) with: {'batch_size': 10, 'max_epochs': 50}
 0.714844 (0.032369) with: {'batch_size': 10, 'max_epochs': 100}
 0.671875 (0.022326) with: {'batch_size': 20, 'max_epochs': 10}
 0.696615 (0.008027) with: {'batch_size': 20, 'max_epochs': 50}
 0.714844 (0.019918) with: {'batch_size': 20, 'max_epochs': 100}
 0.666667 (0.009744) with: {'batch_size': 40, 'max_epochs': 10}
 0.687500 (0.033603) with: {'batch_size': 40, 'max_epochs': 50}
 0.707031 (0.024910) with: {'batch_size': 40, 'max_epochs': 100}
 0.667969 (0.014616) with: {'batch_size': 60, 'max_epochs': 10}
 0.694010 (0.036966) with: {'batch_size': 60, 'max_epochs': 50}
 0.694010 (0.042473) with: {'batch_size': 60, 'max_epochs': 100}
 0.670573 (0.023939) with: {'batch_size': 80, 'max_epochs': 10}
 0.674479 (0.020752) with: {'batch_size': 80, 'max_epochs': 50}
 0.703125 (0.026107) with: {'batch_size': 80, 'max_epochs': 100}
 0.680990 (0.014382) with: {'batch_size': 100, 'max_epochs': 10}
 0.670573 (0.013279) with: {'batch_size': 100, 'max_epochs': 50}
 0.687500 (0.017758) with: {'batch_size': 100, 'max_epochs': 100}
可以看到'batch_size': 10, 'max_epochs': 100达到了约71%的精度的最佳结果。
如何调整训练优化器
下面我们看看如何调整优化器,我们知道有很多个优化器可以选择比如SDG,Adam等,那么如何选择呢?
完整的代码如下:
import numpy as np
 import torch
 import torch.nn as nn
 import torch.optim as optim
 from skorch import NeuralNetClassifier
 from sklearn.model_selection import GridSearchCV

 # load the dataset, split into input (X) and output (y) variables
 dataset = np.loadtxt('pima-indians-diabetes.csv', delimiter=',')
 X = dataset[:,0:8]
 y = dataset[:,8]
 X = torch.tensor(X, dtype=torch.float32)
 y = torch.tensor(y, dtype=torch.float32).reshape(-1, 1)

 # PyTorch classifier
 class PimaClassifier(nn.Module):
def __init__(self):
super().__init__()
self.layer = nn.Linear(8, 12)
self.act = nn.ReLU()
self.output = nn.Linear(12, 1)
self.prob = nn.Sigmoid()

def forward(self, x):
x = self.act(self.layer(x))
x = self.prob(self.output(x))
return x

 # create model with skorch
 model = NeuralNetClassifier(
PimaClassifier,
criterinotallow=nn.BCELoss,
max_epochs=100,
batch_size=10,
verbose=False
 )

 # define the grid search parameters
 param_grid = {
'optimizer': [optim.SGD, optim.RMSprop, optim.Adagrad, optim.Adadelta,
optim.Adam, optim.Adamax, optim.NAdam],
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, y)

 # summarize results
 print("Best: %f using %s" % (grid_result.best_score_, grid_result.best_params_))
 means = grid_result.cv_results_['mean_test_score']
 stds = grid_result.cv_results_['std_test_score']
 params = grid_result.cv_results_['params']
 for mean, stdev, param in zip(means, stds, params):
print("%f (%f) with: %r" % (mean, stdev, param))
输出如下:
Best: 0.721354 using {'optimizer': }
 0.674479 (0.036828) with: {'optimizer': }
 0.700521 (0.043303) with: {'optimizer': }
 0.682292 (0.027126) with: {'optimizer': }
 0.572917 (0.051560) with: {'optimizer': }
 0.714844 (0.030758) with: {'optimizer': }
 0.721354 (0.019225) with: {'optimizer': }
 0.709635 (0.024360) with: {'optimizer': }
可以看到对于我们的模型和数据集Adamax优化算法是最佳的,准确率约为72%。
如何调整学习率
虽然pytorch里面学习率计划可以让我们根据轮次动态调整学习率,但是作为样例,我们将学习率和学习率的参数作为网格搜索的一个参数来进行演示。在PyTorch中,设置学习率和动量的方法如下:
optimizer = optim.SGD(lr=0.001, momentum=0.9)
在skorch包中,使用前缀optimizer__将参数路由到优化器。
import numpy as np
 import torch
 import torch.nn as nn
 import torch.optim as optim
 from skorch import NeuralNetClassifier
 from sklearn.model_selection import GridSearchCV

 # load the dataset, split into input (X) and output (y) variables
 dataset = np.loadtxt('pima-indians-diabetes.csv', delimiter=',')
 X = dataset[:,0:8]
 y = dataset[:,8]
 X = torch.tensor(X, dtype=torch.float32)
 y = torch.tensor(y, dtype=torch.float32).reshape(-1, 1)

 # PyTorch classifier
 class PimaClassifier(nn.Module):
def __init__(self):
super().__init__()
self.layer = nn.Linear(8, 12)
self.act = nn.ReLU()
self.output = nn.Linear(12, 1)
self.prob = nn.Sigmoid()

def forward(self, x):
x = self.act(self.layer(x))
x = self.prob(self.output(x))
return x

 # create model with skorch
 model = NeuralNetClassifier(
PimaClassifier,
criterinotallow=nn.BCELoss,
optimizer=optim.SGD,
max_epochs=100,
batch_size=10,
verbose=False
 )

 # define the grid search parameters
 param_grid = {
'optimizer__lr': [0.001, 0.01, 0.1, 0.2, 0.3],
'optimizer__momentum': [0.0, 0.2, 0.4, 0.6, 0.8, 0.9],
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, y)

 # summarize results
 print("Best: %f using %s" % (grid_result.best_score_, grid_result.best_params_))
 means = grid_result.cv_results_['mean_test_score']
 stds = grid_result.cv_results_['std_test_score']
 params = grid_result.cv_results_['params']
 for mean, stdev, param in zip(means, stds, params):
print("%f (%f) with: %r" % (mean, stdev, param))
结果如下:
Best: 0.682292 using {'optimizer__lr': 0.001, 'optimizer__momentum': 0.9}
 0.648438 (0.016877) with: {'optimizer__lr': 0.001, 'optimizer__momentum': 0.0}
 0.671875 (0.017758) with: {'optimizer__lr': 0.001, 'optimizer__momentum': 0.2}
 0.674479 (0.022402) with: {'optimizer__lr': 0.001, 'optimizer__momentum': 0.4}
 0.677083 (0.011201) with: {'optimizer__lr': 0.001, 'optimizer__momentum': 0.6}
 0.679688 (0.027621) with: {'optimizer__lr': 0.001, 'optimizer__momentum': 0.8}
 0.682292 (0.026557) with: {'optimizer__lr': 0.001, 'optimizer__momentum': 0.9}
 0.671875 (0.019918) with: {'optimizer__lr': 0.01, 'optimizer__momentum': 0.0}
 0.648438 (0.024910) with: {'optimizer__lr': 0.01, 'optimizer__momentum': 0.2}
 0.546875 (0.143454) with: {'optimizer__lr': 0.01, 'optimizer__momentum': 0.4}
 0.567708 (0.153668) with: {'optimizer__lr': 0.01, 'optimizer__momentum': 0.6}
 0.552083 (0.141790) with: {'optimizer__lr': 0.01, 'optimizer__momentum': 0.8}
 0.451823 (0.144561) with: {'optimizer__lr': 0.01, 'optimizer__momentum': 0.9}
 0.348958 (0.001841) with: {'optimizer__lr': 0.1, 'optimizer__momentum': 0.0}
 0.450521 (0.142719) with: {'optimizer__lr': 0.1, 'optimizer__momentum': 0.2}
 0.450521 (0.142719) with: {'optimizer__lr': 0.1, 'optimizer__momentum': 0.4}
 0.450521 (0.142719) with: {'optimizer__lr': 0.1, 'optimizer__momentum': 0.6}
 0.348958 (0.001841) with: {'optimizer__lr': 0.1, 'optimizer__momentum': 0.8}
 0.348958 (0.001841) with: {'optimizer__lr': 0.1, 'optimizer__momentum': 0.9}
 0.444010 (0.136265) with: {'optimizer__lr': 0.2, 'optimizer__momentum': 0.0}
 0.450521 (0.142719) with: {'optimizer__lr': 0.2, 'optimizer__momentum': 0.2}
 0.348958 (0.001841) with: {'optimizer__lr': 0.2, 'optimizer__momentum': 0.4}
 0.552083 (0.141790) with: {'optimizer__lr': 0.2, 'optimizer__momentum': 0.6}
 0.549479 (0.142719) with: {'optimizer__lr': 0.2, 'optimizer__momentum': 0.8}
 0.651042 (0.001841) with: {'optimizer__lr': 0.2, 'optimizer__momentum': 0.9}
 0.552083 (0.141790) with: {'optimizer__lr': 0.3, 'optimizer__momentum': 0.0}
 0.348958 (0.001841) with: {'optimizer__lr': 0.3, 'optimizer__momentum': 0.2}
 0.450521 (0.142719) with: {'optimizer__lr': 0.3, 'optimizer__momentum': 0.4}
 0.552083 (0.141790) with: {'optimizer__lr': 0.3, 'optimizer__momentum': 0.6}
 0.450521 (0.142719) with: {'optimizer__lr': 0.3, 'optimizer__momentum': 0.8}
 0.450521 (0.142719) with: {'optimizer__lr': 0.3, 'optimizer__momentum': 0.9}
对于SGD,使用0.001的学习率和0.9的动量获得了最佳结果,准确率约为68%。
如何激活函数
激活函数控制单个神经元的非线性。我们将演示评估PyTorch中可用的一些激活函数。
import numpy as np
 import torch
 import torch.nn as nn
 import torch.nn.init as init
 import torch.optim as optim
 from skorch import NeuralNetClassifier
 from sklearn.model_selection import GridSearchCV

 # load the dataset, split into input (X) and output (y) variables
 dataset = np.loadtxt('pima-indians-diabetes.csv', delimiter=',')
 X = dataset[:,0:8]
 y = dataset[:,8]
 X = torch.tensor(X, dtype=torch.float32)
 y = torch.tensor(y, dtype=torch.float32).reshape(-1, 1)

 # PyTorch classifier
 class PimaClassifier(nn.Module):
def __init__(self, activatinotallow=nn.ReLU):
super().__init__()
self.layer = nn.Linear(8, 12)
self.act = activation()
self.output = nn.Linear(12, 1)
self.prob = nn.Sigmoid()
# manually init weights
init.kaiming_uniform_(self.layer.weight)
init.kaiming_uniform_(self.output.weight)

def forward(self, x):
x = self.act(self.layer(x))
x = self.prob(self.output(x))
return x

 # create model with skorch
 model = NeuralNetClassifier(
PimaClassifier,
criterinotallow=nn.BCELoss,
optimizer=optim.Adamax,
max_epochs=100,
batch_size=10,
verbose=False
 )

 # define the grid search parameters
 param_grid = {
'module__activation': [nn.Identity, nn.ReLU, nn.ELU, nn.ReLU6,
nn.GELU, nn.Softplus, nn.Softsign, nn.Tanh,
nn.Sigmoid, nn.Hardsigmoid]
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, y)

 # summarize results
 print("Best: %f using %s" % (grid_result.best_score_, grid_result.best_params_))
 means = grid_result.cv_results_['mean_test_score']
 stds = grid_result.cv_results_['std_test_score']
 params = grid_result.cv_results_['params']
 for mean, stdev, param in zip(means, stds, params):
print("%f (%f) with: %r" % (mean, stdev, param))
结果如下:
Best: 0.699219 using {'module__activation': }
 0.687500 (0.025315) with: {'module__activation': }
 0.699219 (0.011049) with: {'module__activation': }
 0.674479 (0.035849) with: {'module__activation': }
 0.621094 (0.063549) with: {'module__activation': }
 0.674479 (0.017566) with: {'module__activation': }
 0.558594 (0.149189) with: {'module__activation': }
 0.675781 (0.014616) with: {'module__activation': }
 0.619792 (0.018688) with: {'module__activation': }
 0.643229 (0.019225) with: {'module__activation': }
 0.636719 (0.022326) with: {'module__activation': }
ReLU激活函数获得了最好的结果,准确率约为70%。
如何调整Dropout参数
在本例中,我们将尝试在0.0到0.9之间的dropout百分比(1.0没有意义)和在0到5之间的MaxNorm权重约束值。
import numpy as np
 import torch
 import torch.nn as nn
 import torch.nn.init as init
 import torch.optim as optim
 from skorch import NeuralNetClassifier
 from sklearn.model_selection import GridSearchCV

 # load the dataset, split into input (X) and output (y) variables
 dataset = np.loadtxt('pima-indians-diabetes.csv', delimiter=',')
 X = dataset[:,0:8]
 y = dataset[:,8]
 X = torch.tensor(X, dtype=torch.float32)
 y = torch.tensor(y, dtype=torch.float32).reshape(-1, 1)

 # PyTorch classifier
 class PimaClassifier(nn.Module):
def __init__(self, dropout_rate=0.5, weight_cnotallow=1.0):
super().__init__()
self.layer = nn.Linear(8, 12)
self.act = nn.ReLU()
self.dropout = nn.Dropout(dropout_rate)
self.output = nn.Linear(12, 1)
self.prob = nn.Sigmoid()
self.weight_constraint = weight_constraint
# manually init weights
init.kaiming_uniform_(self.layer.weight)
init.kaiming_uniform_(self.output.weight)

def forward(self, x):
# maxnorm weight before actual forward pass
with torch.no_grad():
norm = self.layer.weight.norm(2, dim=0, keepdim=True).clamp(min=self.weight_constraint / 2)
desired = torch.clamp(norm, max=self.weight_constraint)
self.layer.weight *= (desired / norm)
# actual forward pass
x = self.act(self.layer(x))
x = self.dropout(x)
x = self.prob(self.output(x))
return x

 # create model with skorch
 model = NeuralNetClassifier(
PimaClassifier,
criterinotallow=nn.BCELoss,
optimizer=optim.Adamax,
max_epochs=100,
batch_size=10,
verbose=False
 )

 # define the grid search parameters
 param_grid = {
'module__weight_constraint': [1.0, 2.0, 3.0, 4.0, 5.0],
'module__dropout_rate': [0.0, 0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9]
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, y)

 # summarize results
 print("Best: %f using %s" % (grid_result.best_score_, grid_result.best_params_))
 means = grid_result.cv_results_['mean_test_score']
 stds = grid_result.cv_results_['std_test_score']
 params = grid_result.cv_results_['params']
 for mean, stdev, param in zip(means, stds, params):
print("%f (%f) with: %r" % (mean, stdev, param))
结果如下:
Best: 0.701823 using {'module__dropout_rate': 0.1, 'module__weight_constraint': 2.0}
 0.669271 (0.015073) with: {'module__dropout_rate': 0.0, 'module__weight_constraint': 1.0}
 0.692708 (0.035132) with: {'module__dropout_rate': 0.0, 'module__weight_constraint': 2.0}
 0.589844 (0.170180) with: {'module__dropout_rate': 0.0, 'module__weight_constraint': 3.0}
 0.561198 (0.151131) with: {'module__dropout_rate': 0.0, 'module__weight_constraint': 4.0}
 0.688802 (0.021710) with: {'module__dropout_rate': 0.0, 'module__weight_constraint': 5.0}
 0.697917 (0.009744) with: {'module__dropout_rate': 0.1, 'module__weight_constraint': 1.0}
 0.701823 (0.016367) with: {'module__dropout_rate': 0.1, 'module__weight_constraint': 2.0}
 0.694010 (0.010253) with: {'module__dropout_rate': 0.1, 'module__weight_constraint': 3.0}
 0.686198 (0.025976) with: {'module__dropout_rate': 0.1, 'module__weight_constraint': 4.0}
 0.679688 (0.026107) with: {'module__dropout_rate': 0.1, 'module__weight_constraint': 5.0}
 0.701823 (0.029635) with: {'module__dropout_rate': 0.2, 'module__weight_constraint': 1.0}
 0.682292 (0.014731) with: {'module__dropout_rate': 0.2, 'module__weight_constraint': 2.0}
 0.701823 (0.009744) with: {'module__dropout_rate': 0.2, 'module__weight_constraint': 3.0}
 0.701823 (0.026557) with: {'module__dropout_rate': 0.2, 'module__weight_constraint': 4.0}
 0.687500 (0.015947) with: {'module__dropout_rate': 0.2, 'module__weight_constraint': 5.0}
 0.686198 (0.006639) with: {'module__dropout_rate': 0.3, 'module__weight_constraint': 1.0}
 0.656250 (0.006379) with: {'module__dropout_rate': 0.3, 'module__weight_constraint': 2.0}
 0.565104 (0.155608) with: {'module__dropout_rate': 0.3, 'module__weight_constraint': 3.0}
 0.700521 (0.028940) with: {'module__dropout_rate': 0.3, 'module__weight_constraint': 4.0}
 0.669271 (0.012890) with: {'module__dropout_rate': 0.3, 'module__weight_constraint': 5.0}
 0.661458 (0.018688) with: {'module__dropout_rate': 0.4, 'module__weight_constraint': 1.0}
 0.669271 (0.017566) with: {'module__dropout_rate': 0.4, 'module__weight_constraint': 2.0}
 0.652344 (0.006379) with: {'module__dropout_rate': 0.4, 'module__weight_constraint': 3.0}
 0.680990 (0.037783) with: {'module__dropout_rate': 0.4, 'module__weight_constraint': 4.0}
 0.692708 (0.042112) with: {'module__dropout_rate': 0.4, 'module__weight_constraint': 5.0}
 0.666667 (0.006639) with: {'module__dropout_rate': 0.5, 'module__weight_constraint': 1.0}
 0.652344 (0.011500) with: {'module__dropout_rate': 0.5, 'module__weight_constraint': 2.0}
 0.662760 (0.007366) with: {'module__dropout_rate': 0.5, 'module__weight_constraint': 3.0}
 0.558594 (0.146610) with: {'module__dropout_rate': 0.5, 'module__weight_constraint': 4.0}
 0.552083 (0.141826) with: {'module__dropout_rate': 0.5, 'module__weight_constraint': 5.0}
 0.548177 (0.141826) with: {'module__dropout_rate': 0.6, 'module__weight_constraint': 1.0}
 0.653646 (0.013279) with: {'module__dropout_rate': 0.6, 'module__weight_constraint': 2.0}
 0.661458 (0.008027) with: {'module__dropout_rate': 0.6, 'module__weight_constraint': 3.0}
 0.553385 (0.142719) with: {'module__dropout_rate': 0.6, 'module__weight_constraint': 4.0}
 0.669271 (0.035132) with: {'module__dropout_rate': 0.6, 'module__weight_constraint': 5.0}
 0.662760 (0.015733) with: {'module__dropout_rate': 0.7, 'module__weight_constraint': 1.0}
 0.636719 (0.024910) with: {'module__dropout_rate': 0.7, 'module__weight_constraint': 2.0}
 0.550781 (0.146818) with: {'module__dropout_rate': 0.7, 'module__weight_constraint': 3.0}
 0.537760 (0.140094) with: {'module__dropout_rate': 0.7, 'module__weight_constraint': 4.0}
 0.542969 (0.138144) with: {'module__dropout_rate': 0.7, 'module__weight_constraint': 5.0}
 0.565104 (0.148654) with: {'module__dropout_rate': 0.8, 'module__weight_constraint': 1.0}
 0.657552 (0.008027) with: {'module__dropout_rate': 0.8, 'module__weight_constraint': 2.0}
 0.428385 (0.111418) with: {'module__dropout_rate': 0.8, 'module__weight_constraint': 3.0}
 0.549479 (0.142719) with: {'module__dropout_rate': 0.8, 'module__weight_constraint': 4.0}
 0.648438 (0.005524) with: {'module__dropout_rate': 0.8, 'module__weight_constraint': 5.0}
 0.540365 (0.136861) with: {'module__dropout_rate': 0.9, 'module__weight_constraint': 1.0}
 0.605469 (0.053083) with: {'module__dropout_rate': 0.9, 'module__weight_constraint': 2.0}
 0.553385 (0.139948) with: {'module__dropout_rate': 0.9, 'module__weight_constraint': 3.0}
 0.549479 (0.142719) with: {'module__dropout_rate': 0.9, 'module__weight_constraint': 4.0}
 0.595052 (0.075566) with: {'module__dropout_rate': 0.9, 'module__weight_constraint': 5.0}
可以看到,10%的Dropout和2.0的权重约束获得了70%的最佳精度。
如何调整隐藏层神经元的数量
单层神经元的数量是一个需要调优的重要参数。一般来说,一层神经元的数量控制着网络的表示能力,至少在拓扑的这一点上是这样。
理论上来说:由于通用逼近定理,一个足够大的单层网络可以近似任何其他神经网络。
在本例中,将尝试从1到30的值,步骤为5。一个更大的网络需要更多的训练,至少批大小和epoch的数量应该与神经元的数量一起优化。
import numpy as np
 import torch
 import torch.nn as nn
 import torch.nn.init as init
 import torch.optim as optim
 from skorch import NeuralNetClassifier
 from sklearn.model_selection import GridSearchCV

 # load the dataset, split into input (X) and output (y) variables
 dataset = np.loadtxt('pima-indians-diabetes.csv', delimiter=',')
 X = dataset[:,0:8]
 y = dataset[:,8]
 X = torch.tensor(X, dtype=torch.float32)
 y = torch.tensor(y, dtype=torch.float32).reshape(-1, 1)

 class PimaClassifier(nn.Module):
def __init__(self, n_neurnotallow=12):
super().__init__()
self.layer = nn.Linear(8, n_neurons)
self.act = nn.ReLU()
self.dropout = nn.Dropout(0.1)
self.output = nn.Linear(n_neurons, 1)
self.prob = nn.Sigmoid()
self.weight_constraint = 2.0
# manually init weights
init.kaiming_uniform_(self.layer.weight)
init.kaiming_uniform_(self.output.weight)

def forward(self, x):
# maxnorm weight before actual forward pass
with torch.no_grad():
norm = self.layer.weight.norm(2, dim=0, keepdim=True).clamp(min=self.weight_constraint / 2)
desired = torch.clamp(norm, max=self.weight_constraint)
self.layer.weight *= (desired / norm)
# actual forward pass
x = self.act(self.layer(x))
x = self.dropout(x)
x = self.prob(self.output(x))
return x

 # create model with skorch
 model = NeuralNetClassifier(
PimaClassifier,
criterinotallow=nn.BCELoss,
optimizer=optim.Adamax,
max_epochs=100,
batch_size=10,
verbose=False
 )

 # define the grid search parameters
 param_grid = {
'module__n_neurons': [1, 5, 10, 15, 20, 25, 30]
 }
 grid = GridSearchCV(estimator=model, param_grid=param_grid, n_jobs=-1, cv=3)
 grid_result = grid.fit(X, y)

 # summarize results
 print("Best: %f using %s" % (grid_result.best_score_, grid_result.best_params_))
 means = grid_result.cv_results_['mean_test_score']
 stds = grid_result.cv_results_['std_test_score']
 params = grid_result.cv_results_['params']
 for mean, stdev, param in zip(means, stds, params):
print("%f (%f) with: %r" % (mean, stdev, param))
结果如下:
Best: 0.708333 using {'module__n_neurons': 30}
 0.654948 (0.003683) with: {'module__n_neurons': 1}
 0.666667 (0.023073) with: {'module__n_neurons': 5}
 0.694010 (0.014382) with: {'module__n_neurons': 10}
 0.682292 (0.014382) with: {'module__n_neurons': 15}
 0.707031 (0.028705) with: {'module__n_neurons': 20}
 0.703125 (0.030758) with: {'module__n_neurons': 25}
 0.708333 (0.015733) with: {'module__n_neurons': 30}
你可以看到,在隐藏层中有30个神经元的网络获得了最好的结果,准确率约为71%。

机器学习奠基人MichaelJordan认为AGI是公关炒作,AI的真正挑战在于让系统学会协调。他主张机器学习必须与经济学结合,关注不确定性、激励机制和数据流动等社会系统性问题,而非单纯追求模型能力。

持续坚持原创输出,点击蓝字关注我吧 ❝ 沉淀、分享、成长,让自己和他人都能有所收获! ❞ 目录 一、前言二、面试题三、线程池讲解1. 先看个例子2. 手写一个线程池3. 线程池源码分析四、总结五、系列推荐一、前言人看手机,机器学习!正好是2020年,看到这张图还是蛮有意思的。以前小时候总会看到一些科

当前数字时代,deepseek入口智能助手凭借前沿技术架构为用户带来革新体验 在如今这个数字浪潮翻涌的时代,deepseek入口智能助手凭借其前沿的技术架构,为用户带来了真正意义上的革新体验。这个平台巧妙融合了自然语言处理与知识图谱技术,能够精准解析那些看似复杂的语义需求,已然成为提升工作效率的智能
刚开始学机器学习时,我也像大部分人 一样,有个很朴素的想法:特征越多,模型能学到的信息就越多,效果自然越好。 所以每次拿到数据,我就拼命往模型里塞特征——能算出来的统计量全加上,能衍生出来的比率全拼上。 一个原本 20 列的数据集,经常被我搞到七八十列。 然后我就发现事情不太对劲了: 训练时间明显变
机器学习实战中,大家往往把精力花在调参和选模型上,却忽略了一个更基础的问题:喂给模型的数据里,有多少特征是真正有用的? 刚开始学机器学习那会儿,很多人特别喜欢堆特征——不管有用没用先一股脑全塞进去,总觉得特征越多模型越聪明。直到有一次跑练习数据集,X_train.shape 直接干到了 (50000
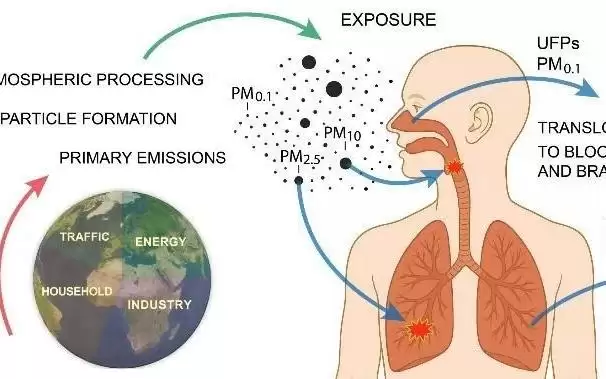
空气中直径小于100纳米的超细颗粒物每年导致约199万人早逝,其中近半因心血管疾病。该颗粒物主要来自化石燃料,可通过呼吸进入血液,引发氧化应激和内皮功能紊乱,是未被充分认识的心血管危险因素。若年均浓度控制在每立方厘米5000个以下,全球超额死亡率可降低约45%。
这项研究来自Ezgi Korkmaz,论文以预印本形式发布于2026年7月8日,编号为arXiv:2607.07769,发表于cs.LG(机器学习)领域,并将出版于2026年人工智能促进协会(AAAI)会议论文集。有兴趣深入了解的读者可以通过arXiv编号2607.07769查询完整论文。 深度强化
机器人编程侧重硬件组装与程序驱动,编程受限于特定机器人;少儿编程系统化教授编程知识,从Scratch启蒙延伸至Python、C++等高级语言。两者各有侧重,选择取决于希望孩子提升的能力方向。
少儿编程分为软件与硬件两大方向。软件编程侧重逻辑与代码能力,含图形化、Python、C++,适配学业竞赛;硬件编程侧重动手与工程实践,含乐高搭建与机器人。选择应基于孩子兴趣与年龄。






火山引擎是字节跳动旗下企业级云与AI服务平台。聚焦大模型核心能力,依托字节自研豆包多模态大模型,凭借火山方舟一站式平台,提供模型精调、推理部署、智能应用搭建等全链路服务,结合高性能AI算力,助力各行业快速落地大模型数字化与智能化应用。



